Custom AI insights
AI Exception Monitoring for Small Business: Catch Problems Before They Become Fire Drills
AI exception monitoring watches for the small set of business conditions that deserve attention, then adds context and routes the issue to a responsible person.
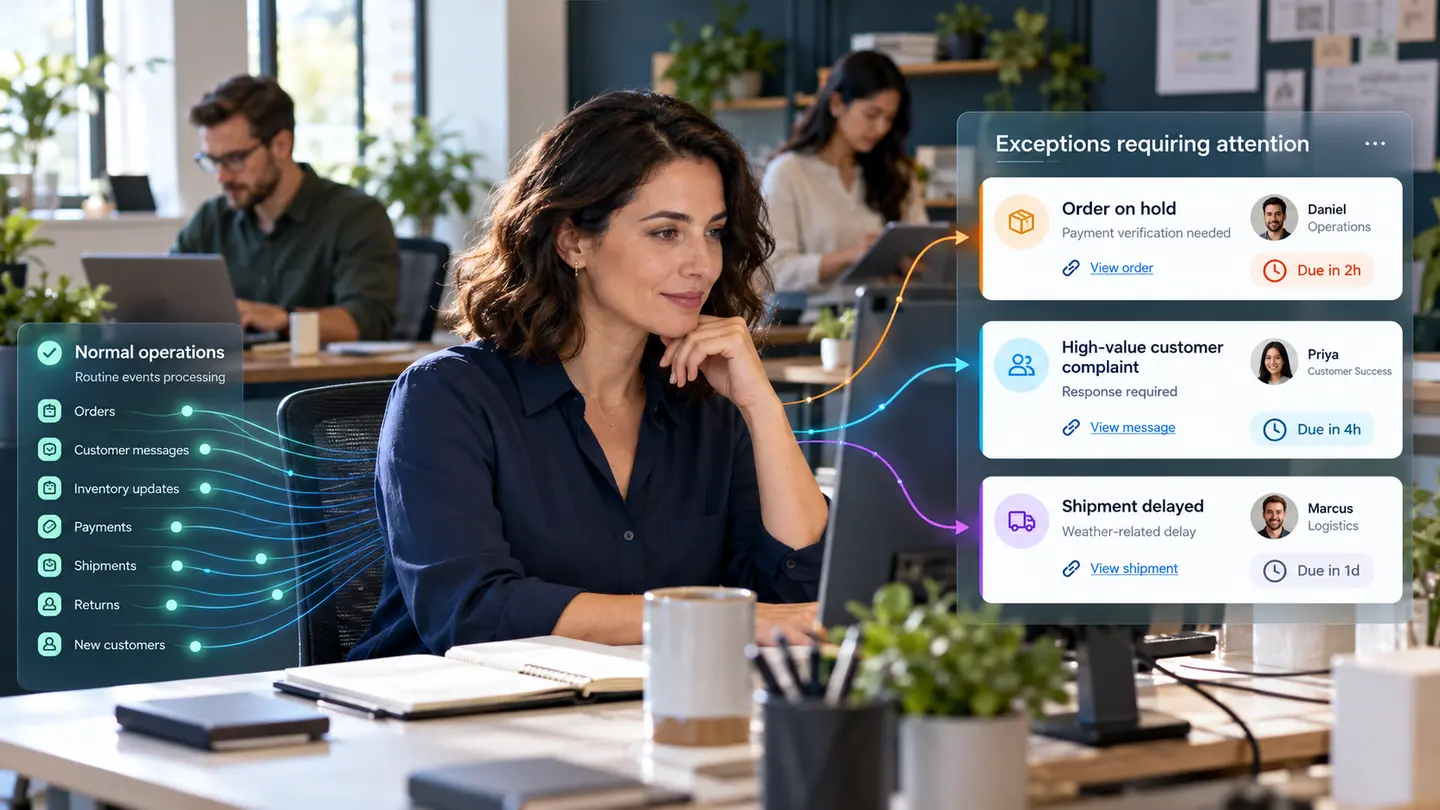
Most business dashboards are built to show everything. The problem is that owners and managers rarely have time to watch everything.
An overdue work order, unanswered lead, failed payment, inventory shortage, missed deadline, unusual refund pattern, or broken integration may sit quietly until a customer complains or a routine issue becomes expensive.
AI exception monitoring is a more focused approach. Instead of asking a person to review every record, the system watches approved sources for conditions that deserve attention, gathers the surrounding context, and routes the issue to someone who can decide what to do.
An Exception Is Different From a Report
A weekly report summarizes what happened over a period of time. A dashboard gives someone a place to look. Exception monitoring is designed for the smaller set of situations that should interrupt the normal flow of work.
That distinction matters. A report might show average response time. An exception monitor identifies the three leads that have waited beyond the agreed limit and tells the owner who they are, how they arrived, and whether anyone has already tried to respond.
Choose Conditions Worth Interrupting Someone For
Not every unusual event deserves an alert. Start with conditions that are costly, customer-visible, time-sensitive, or hard to recover from. Examples include a high-value estimate with no follow-up, a job scheduled without required information, a payment failure on an active account, or a customer message that mentions safety or cancellation.
Define the rule in business language first. What happened? How long can it wait? Who owns the response? What context is required? What should happen outside business hours? If the team cannot explain why an alert matters, the system will probably create noise instead of control.
Expiration monitoring can catch certificate and license renewals before they interrupt work.
Use Trusted Systems for the Facts
The monitoring workflow should read from the tools that already own the information: the CRM for lead status, the calendar for appointments, the help desk for open issues, the accounting system for payment state, or the project platform for due dates.
AI can help interpret unstructured notes, emails, or descriptions, but exact facts such as balances, dates, ownership, and status should come from the authoritative system whenever possible. If a source is unavailable or stale, the alert should say so rather than filling the gap with a guess.
Let AI Add Context, Not Invent Urgency
Traditional rules are good at clear conditions: a task is three days overdue, a required field is blank, or a payment failed twice. AI becomes useful when the system needs to understand language, group related events, summarize a history, or distinguish a routine request from a potentially serious complaint.
The safest design combines both. Rules determine when a known condition has been met. AI prepares a concise explanation using approved sources. A person remains responsible for judgment, priority changes, customer commitments, refunds, disciplinary action, or other high-impact decisions.
Make Every Alert Actionable
An alert that says “something may be wrong” creates a second investigation. A useful alert says what happened, why it was flagged, which customer or process is affected, which source records support it, who owns the next step, and when a response is due.
Whenever practical, link the alert back to the original record. The recipient should be able to verify the summary instead of trusting it blindly. For routine exceptions, the system may prepare a task or draft response, but sending or committing should follow the business’s approval rules.
Next, combine exception alerts with an actionable review queue.
Prevent Alert Fatigue
The fastest way to ruin a monitoring system is to make it noisy. Duplicate alerts, low-value warnings, and repeated reminders teach people to ignore the channel.
Group related events into one case, suppress duplicates, and decide when an issue should be reminded, escalated, or closed. Track which alerts led to action and which were dismissed. If a condition rarely matters, tighten the rule or remove it. The goal is a short queue of meaningful exceptions, not proof that the system is watching.
Keep Ownership, Logs, and Human Review Clear
Every exception category needs an owner. The system can route and summarize, but someone must be accountable for resolving the issue and correcting the underlying process when the same exception repeats.
Logs should show the source data, the rule or classification that triggered the alert, the recipients, and the final disposition. Review false positives and missed events regularly. That feedback is how the workflow becomes more useful without silently expanding its authority.
Start With One Costly Exception
Do not begin by monitoring the entire business. Choose one exception that already causes delays, lost revenue, customer frustration, or repeated management checking. Measure how often it occurs, how long it currently takes to notice, and what a better response would look like.
Turn low-stock alerts into a reviewable reorder recommendation before a routine exception becomes a stockout.
Custom AI By Design can help map that exception, connect the right sources, define alert rules and escalation paths, and build a focused system that tells your team what needs attention without asking them to watch another dashboard all day.
Stop Watching Everything. Monitor What Matters.
Choose one business condition that is expensive to notice late. We can help connect the right sources, define a useful alert, and keep the response owned by your team.
Map an Exception Workflow ↗